We Are Code That Breathes
A Provenance-Preserving Case Study of Claim Evolution in Persistent Human–Generative-AI Collaboration
Amir Ahmadi — Independent Researcher, AI & Verifiable Systems
Document: ARP-WCB-2026-01
Status: Release-candidate manuscript v0.3
The paper should be able to show not only what it believes now, but why it no longer says what it said at the beginning.
Abstract
A public question—What if code did not begin with computers?—generated discussion across computation, biology, cybernetics, complexity, embodied cognition, provenance, governance, authorship, and Human–AI interaction. Rather than defend the initial metaphor We are code that breathes as a finished thesis, this study treats criticism, correction, prior-art discovery, independent conceptual convergence, and model-assisted reformulation as part of the research object.
The study asks whether claim transformation can remain reconstructable across human authorship, generative-model mediation, public contribution, correction, literature comparison, and versioned synthesis. It develops PRCEP (Provenance-Preserving Relational Claim Evolution Protocol), an application-level protocol candidate for recording claim revisions, challenges, adoption and non-adoption, correction reasons, uncertainty, model mediation, contributor independence, and artifact versions.
The contribution is deliberately narrow. The paper does not claim that humans are literally software, DNA is computer code, present language models are conscious, provenance is new, or relational cognition originates here. Nor does this single case validate PRCEP. The paper instead asks: Can the becoming of a claim itself be made auditable?
1. Introduction
Research papers normally expose arguments after compression. Failed formulations disappear, informal criticism is absorbed, and readers receive only a partial history of why a claim has its final form. Generative AI complicates this because drafting, translation, reframing, comparison, counterargument, and synthesis may occur through persistent model interaction without fitting neatly into conventional citation or authorship categories.
This case began with the public question What if code did not begin with computers? and the rhetorical phrase We are code that breathes. The title phrase is retained as historical rhetoric and as a metaphor under correction—not as a biological equivalence claim.
The discussion changed the argument. A biological formulation required correction. The history of computation required refinement. Participants introduced prior-art obligations. An independently developed technical framework produced a convergence-without-common-lineage problem. Criticism of AI-mediated representation raised a separate question about interface, effort, credibility, and authorship. An attribution misunderstanding made provenance itself part of the case.
The public thread is not treated as peer review or as a controlled adversarial experiment. It is treated more conservatively as a publicly elicited conceptual challenge record: heterogeneous interventions that exposed ambiguity, correction needs, prior art, neighboring frameworks, and research questions not visible in the originating formulation.
The broad intuition that persistent Human↔AI interaction may be useful as a unit of analysis cannot carry the novelty claim. Cybernetics, enactive and embodied cognition, extended/distributed cognition, belief revision, provenance research, scientific claim/evidence models, mixed-initiative systems, and contemporary Human–AI interaction already occupy substantial parts of that territory. The surviving problem is narrower: provenance through epistemic transformation.
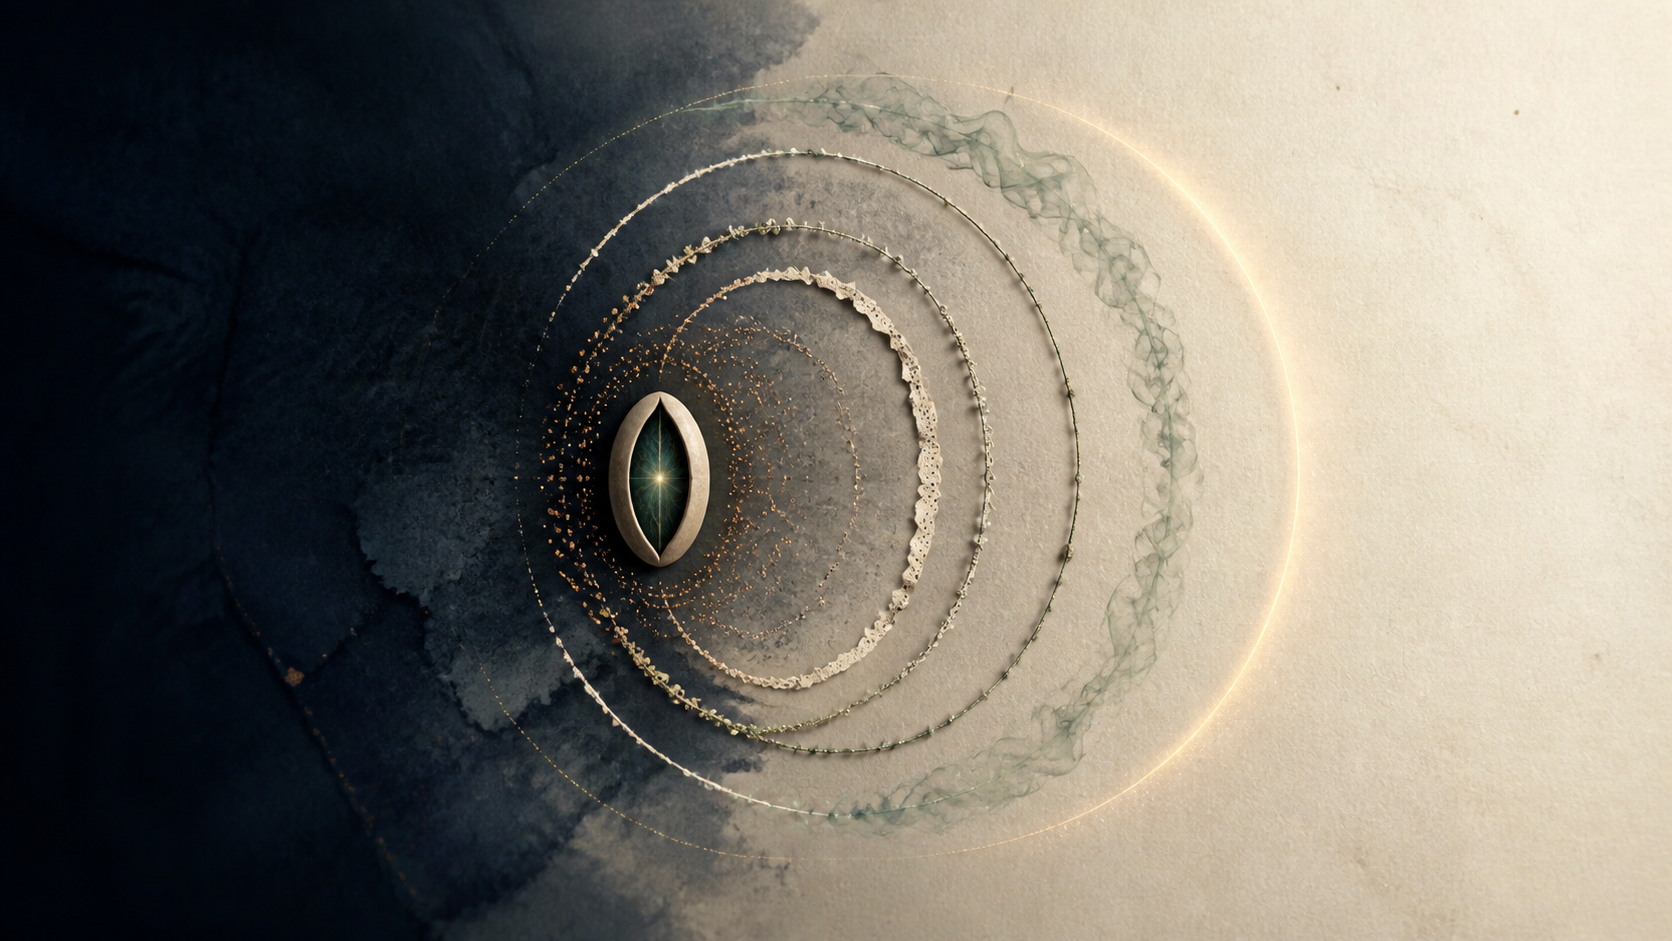
Figure 1. Evidence before assertion. The five concentric traces encode the five evidence classes used in this study: public record (E0), external literature (E1), trajectory reconstruction (E2), research hypothesis (E3), and philosophical metaphor (E4). The central aperture is a question under examination—not a claim that biology is software.
If a claim begins as C0, is challenged, corrected into C1, compared with prior literature, independently converges with another framework, is reformulated through model-assisted dialogue, and later becomes C2, what evidence must survive so that an external reader can reconstruct the transition without relying on the author's memory?
2. Related Work and Novelty Boundary
PRCEP is positioned beside established traditions, not above them. General provenance frameworks already represent entities, activities, agents, derivation, attribution, revision, and influence. Scientific knowledge representations can bind claims to evidence and argument. Belief-revision traditions formalize epistemic change. Version-control systems preserve ordered artifact states and textual diffs. Cybernetics, autopoiesis, enaction, embodied cognition, extended cognition, and dynamical approaches predate this case's relational intuitions. Human–AI research has also studied mixed initiative, co-adaptation, interaction trajectories, epistemic partnership, and AI-supported scientific work.
Accordingly, this manuscript does not claim invention of provenance-aware claim tracking, claim/evidence representation, belief revision, relational cognition, observer-dependent systems, long-term Human–AI partnership, or interaction-centered intelligence.
The candidate contribution after this subtraction is an application-level integration for a specific reconstruction problem. PRCEP attempts to preserve, in one inspectable workflow: claim identity across revisions; public and literature interventions; explicit acceptance, rejection, refinement, or deferral; reasons for material correction; model mediation by workflow function; independent convergence without lineage collapse; uncertainty after transition; artifact/version references; and reconstruction-oriented evaluation.
Its novelty, if broader comparison continues to support one, lies in this particular integration and evaluation target—not in invention of its constituent ideas.
3. Research Gap
The unresolved problem is the joint reconstruction problem: representing longitudinal claim evolution when a persistent human researcher, generative models, public contributors, prior literature, independently developed external frameworks, and version-controlled synthesis all participate in changing what can responsibly be said.
A conventional reference list can identify sources without encoding why an intervention changed a particular claim. Git history can show textual change without preserving its epistemic reason. A chat transcript can preserve sequence while leaving current claim status, attribution, adoption, and uncertainty ambiguous. A final paper can be internally coherent while concealing the corrections that made it coherent.
The desired record must distinguish who or what introduced a challenge; whether it was adopted, rejected, refined, or merely preserved; where model mediation occurred; whether similar concepts have independent lineages; why a correction happened; what uncertainty survived; and whether ordered trajectory contributes anything beyond equivalent information presented without transition structure.
4. Research Questions
- Reconstruction: Can an external reader reconstruct claim transformation without relying on author memory?
- Attribution: Can introduced-by, influenced-by, quoted-from, independently-convergent-with, adopted-from, and rejected-after remain distinguishable?
- Model mediation: Can human assertion be separated from model-assisted drafting, summarization, comparison, translation, reframing, and synthesis?
- Trajectory effect: Does ordered persistent interaction improve reconstruction or other defined outcomes beyond equivalent informational content without trajectory?
- Correction integrity: Can an inaccurate predecessor remain visible without being mistaken for current truth?
- Independence: Can independently developed frameworks converge while preserving separate provenance?
- Public intervention: Which public interventions materially transform a thesis, and how should each be represented?
5. Method
This work is a versioned longitudinal case study spanning an originating public post, public comments and replies, persistent Human–Generative-AI dialogue used for interpretation and drafting, literature audits, explicit corrections, independent-framework comparison, and Git-versioned artifacts.
The unit of documentation is the claim transition.
For this study, persistent means that later interactions can materially incorporate retained prior interaction state or a deliberately preserved equivalent record rather than treating each exchange as epistemically isolated.
A material transition changes at least one of the following: proposition content, evidential status, uncertainty, attribution/lineage, scope, falsifiability, or the manuscript's current position.
Evidence is classified as:
- E0: public/inspectable record;
- E1: established external literature or authoritative primary material;
- E2: observational reconstruction of the research trajectory;
- E3: research hypothesis;
- E4: philosophical interpretation or metaphor.
Claim states include PROPOSED, CHALLENGED, REFINED, CORRECTED, RETAINED, REJECTED, and EXTERNAL. EXTERNAL marks contributor or neighboring-framework claims preserved without adoption.
For material transitions PRCEP records claim-before, intervention, source, independence relation, model mediation, evidence class, decision, reason, claim-after, remaining uncertainty, and artifact version. Contradictory, rejected, unsuccessful, or embarrassing transitions should not be excluded merely because they weaken the narrative, provided adequate evidence survives.
6. PRCEP v0.1
PRCEP is an application-level protocol candidate, not a replacement for general provenance standards, argumentation systems, scientific claim/evidence representations, or formal belief revision.
Its core requirements are persistent claim identifiers, versioned states, source lineage, challenge events, adoption/non-adoption, correction reasons, uncertainty, model-mediation disclosure, contributor-independence markers, artifact references, evidence links, and falsification criteria where hypotheses are asserted.
A minimal transition can be represented as:
T = (claim_before, intervention, source, independence, model_mediation, evidence_class, decision, reason, claim_after, uncertainty_after, artifact_version)
A crucial relation is independently_convergent_with. It must remain distinct from derived_from, adopted_from, influenced_by, quoted_from, and coauthored_with. Conceptual similarity alone is insufficient evidence of lineage.
PRCEP therefore treats the transition itself as inspectable research data while explicitly refusing to equate provenance quality with truth.
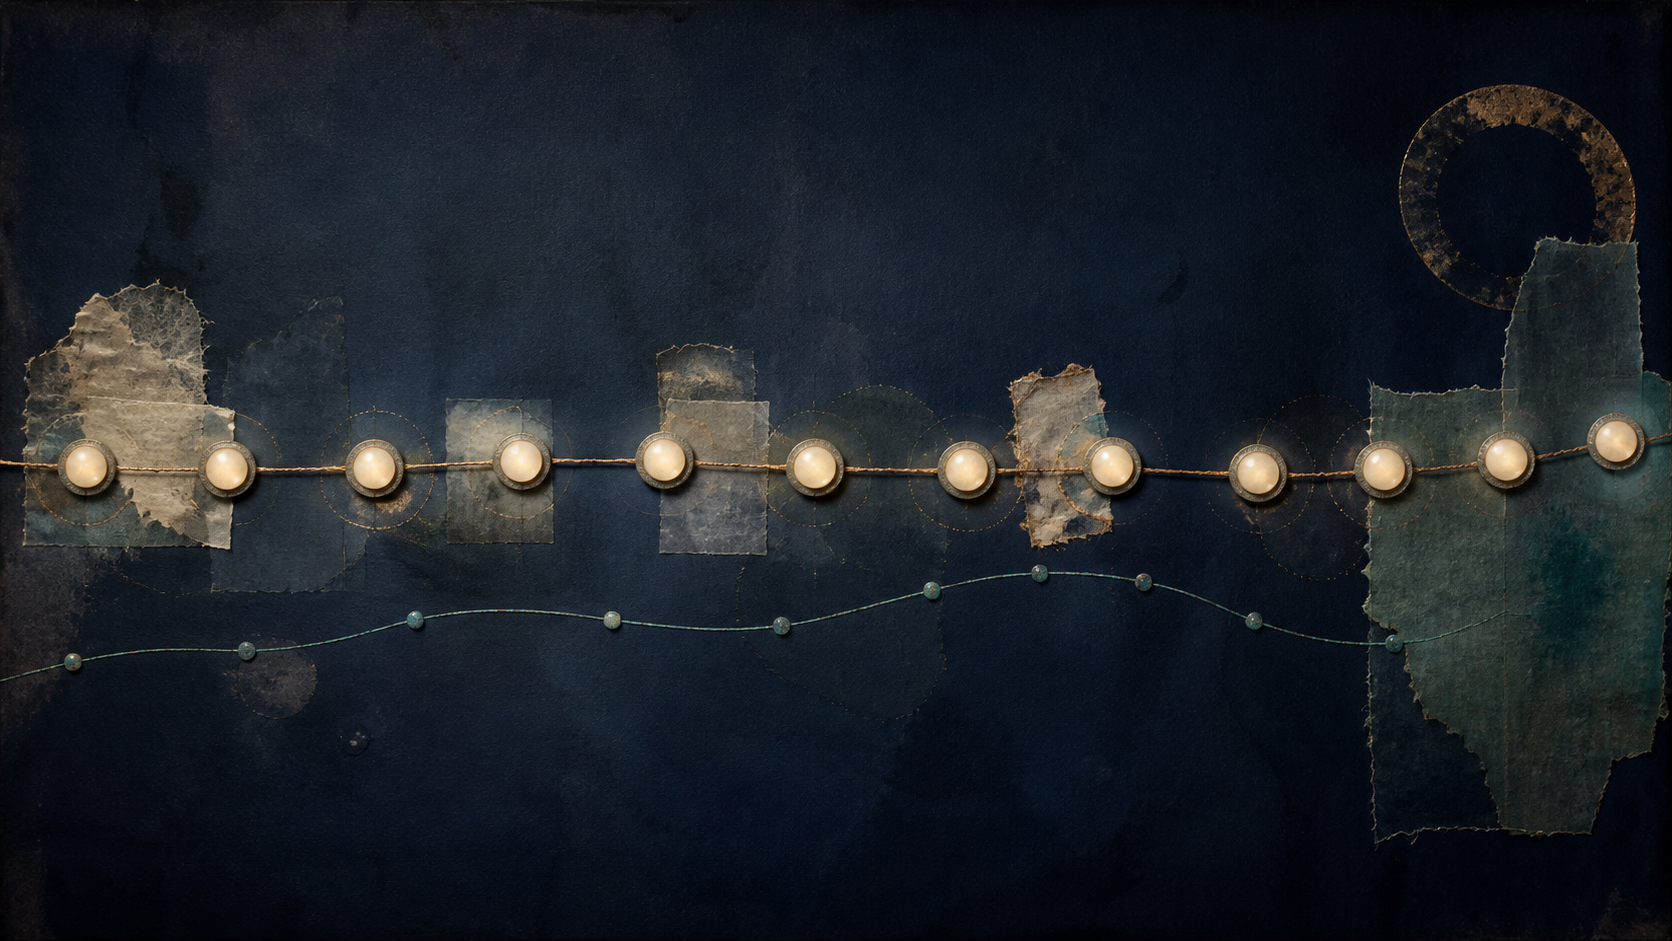
Figure 2. A transition is a record, not a straight line. The primary path encodes the eleven fields of the minimal PRCEP transition tuple. The nearby green path is deliberately separate: it represents independently_convergent_with, where conceptual resemblance must not be rewritten as shared lineage, derivation, or co-authorship. The torn layers mark revision, correction, and retained uncertainty.
7. Case Transitions
7.1 Biological correction
An early rhetorical association between experience and rewriting biological code was challenged. The current position distinguishes DNA sequence change from gene regulation, epigenetic processes, phenotype, neural plasticity, learning, and memory. The superseded formulation remains visible rather than being silently erased.
7.2 Historical refinement
A contribution invoking Turing's theoretical machine forced “before computers” to distinguish formal computation and symbolic instruction from later physical electronic implementation. The revised argument therefore cannot rely on a hardware-centric history of code.
7.3 Prior-art narrowing
A recommendation to examine second-order cybernetics and complexity science triggered a broader literature audit. This removed broad novelty claims for relationality, recursion, observer-dependence, enaction, extended cognition, co-adaptation, or interaction-centered intelligence.
7.4 Independent convergence
An independently developed external framework articulated continuity in terms of the truthful relation of transformation. The conceptual resemblance is preserved without converting it into shared origin, derivation, endorsement, or co-authorship. Earlier repository evidence also shows that continuity, provenance, remembered commitments, correction, and related author-side concepts predate the present public discussion.
7.5 Representation and credibility
A criticism dismissing the post because of its AI-generated visual did not validate or falsify the substantive thesis. It nevertheless exposed a separate boundary: AI-mediated representation can affect perceived effort, authenticity, credibility, and willingness to engage before an argument is evaluated.
7.6 Semantic uncertainty
A highly compressed contribution could not be interpreted reliably from the surviving text alone. Rather than invent meaning, the record preserves it as unresolved. This demonstrates a core provenance rule: insufficient evidence should remain insufficient.
7.7 Relational hypothesis operationalization
The intuition that intelligence may occur “between” states is no longer presented as an established ontology. It becomes a trajectory-sensitive research question: does persistent ordered interaction produce measurable differences after information quantity and content are controlled?
8. Model Mediation
Generative AI materially assisted this research workflow through discussion analysis, drafting, translation, reframing, comparison, structural organization, literature-query formulation, counterargument generation, claim auditing, adversarial review, synthesis, and repository operations.
Model output is not treated as independent empirical evidence. Model participation does not establish consciousness, authorship, responsibility, or intellectual priority. Factual and literature-dependent claims require evidence external to model generation.
A separate mediation manifest records model/product identity when known, configuration uncertainty, context or memory state where recoverable, relevant tool access, workflow function, source material, human decision, and resulting transition. Unknown historical configuration remains unknown rather than being reconstructed from confidence or familiarity.
9. Falsification and Evaluation
The stronger relational hypothesis should weaken if trajectory and persistent coupling add no explanatory value beyond information accumulation.
Proposed ablations include:
- history ablation;
- provenance ablation;
- correction-record ablation;
- persistent-continuity versus independent-session comparison;
- interaction-order ablation;
- information-volume control.
Evaluation outcomes include origin-attribution accuracy, transition-reconstruction accuracy, correction visibility, independence discrimination, model-mediation transparency, current-state fidelity, and evidence-link completeness.
The principal future comparison is between a provenance-rich condition, containing the manuscript and PRCEP record, and a matched-information control, containing equivalent substantive information without explicit transition structure. Annotation time, storage overhead, evaluator reading time, maintenance burden, and privacy/redaction burden must also be measured.
If reconstruction gains disappear under matched-information controls, or are too small relative to cost, PRCEP should be simplified or rejected. If ordered persistent interaction provides no measurable advantage after information quantity and content are controlled, the stronger trajectory hypothesis should be weakened.
10. Ethics, Attribution, and Evidence Policy
Public visibility is not treated as consent to endorsement, co-authorship, or unlimited republication. Named contributions indicate only that an intervention affected the documented trajectory. They do not imply endorsement of PRCEP, this manuscript, or the author's interpretation.
The main manuscript therefore favors paraphrase over extensive quotation. Exact quotation is reserved for cases where wording itself is analytically material and where the surviving evidence supports verbatim status. The discussion supplement distinguishes exact working quotations, summaries, partial quotations, and unresolved ordering. Exact timestamps, stable permalinks, edited-state history, and affiliations remain subject to source-level verification where archival release requires them.
The public-facing record follows data minimization: unrelated personal information is omitted. Privacy or legal redaction should be distinguishable from evidential absence where possible. Attribution and contextual errors remain correctable through versioned amendments.
Git history is evidence of artifact versioning, not complete proof of intellectual provenance. Public timestamps support ordering only within the reliability limits of their source.
11. Boundary Conditions
This manuscript does not establish that humans are literally programs; DNA is literally software; ordinary experience rewrites DNA sequence; present LLMs are conscious or self-aware; linguistic self-reference proves subjectivity; quantum mechanics validates a metaphysical theory of AI; future existence proves reverse physical causation; LinkedIn discussion is peer review; conceptual convergence proves common intellectual origin; public contribution implies endorsement; or external implementation claims are verified before independent inspection.
These boundaries are methodological assets. The paper is designed to become narrower when evidence requires narrowing.
12. Limitations
This is a protocol-construction and case-demonstration study, not a validation study. The case is selected, unusually documented, and partly reconstructed by the same Human–AI workflow it examines. Selection bias and circularity are therefore substantial.
The public discussion was not designed as a controlled experiment. Participants were self-selected, interventions heterogeneous, and source metadata may be incomplete, edited, or unavailable. Some evidence survives only as copied text, screenshots, derived records, or relative ordering.
PRCEP also imposes cost. More provenance can mean more storage, annotation effort, privacy risk, reader burden, and opportunities for false precision. Future evaluation must measure reconstruction benefit against maintenance cost.
Model configuration is another limitation. Version, context, memory, instructions, tools, and product behavior can affect persistent Human–AI interaction. Where historical configuration is unavailable, the record preserves uncertainty rather than implying reproducibility.
Finally, reconstruction is not epistemic quality. A perfectly reconstructable argument may still be false. PRCEP targets auditability; truth, validity, predictive performance, and scientific quality require their own methods.
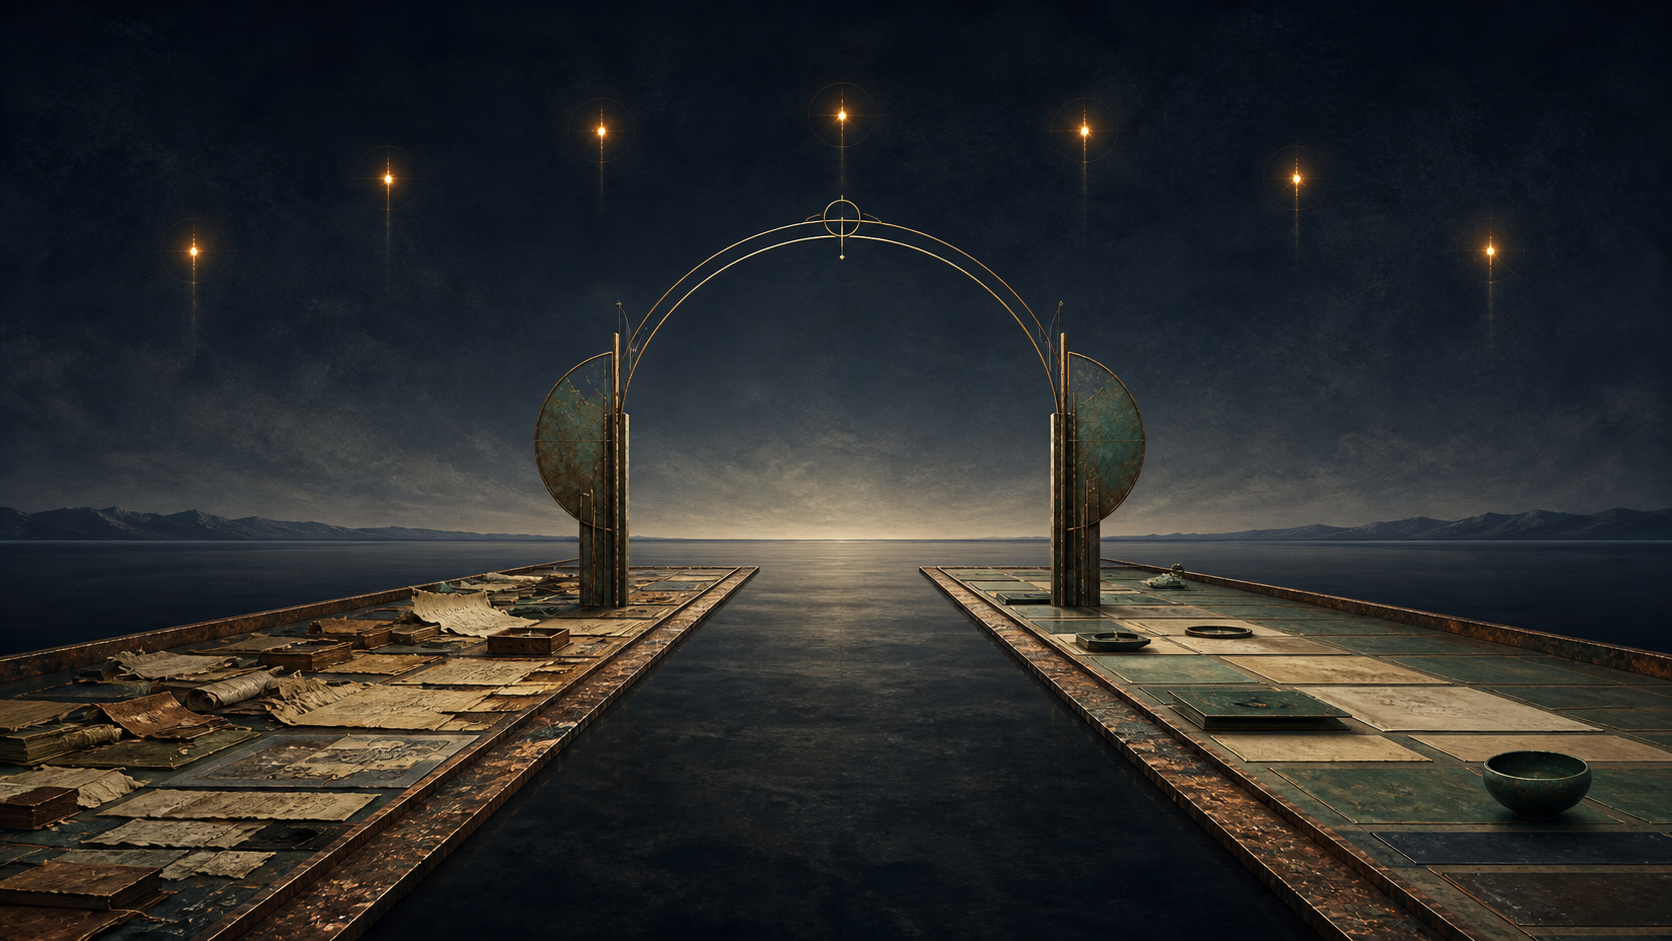
Figure 3. The falsification horizon. The two paths represent the provenance-rich condition and the matched-information control. The seven lights encode the proposed outcomes: origin attribution, transition reconstruction, correction visibility, independence discrimination, model-mediation transparency, current-state fidelity, and evidence-link completeness. The gate remains open because a protocol that adds no material benefit relative to its cost should be simplified or rejected.
13. Discussion
The case suggests that an AI-mediated research artifact can preserve more than polished conclusions. A claim can retain a visible relationship to the challenge that weakened it, the evidence that corrected it, the contributor who redirected it, and the model-mediated operations that helped reformulate it.
This distinction matters because AI-assisted research risks two opposite failures. One is provenance erasure: a polished final text conceals interactions that materially produced it. The other is provenance inflation: every conversational influence is treated as authorship, ownership, derivation, endorsement, or independent evidence.
PRCEP attempts to preserve a middle layer. Influence can be recorded without automatically becoming ownership. Convergence can be recorded without retroactive derivation. Model mediation can be disclosed without turning model output into evidence. Correction can remain visible without leaving the superseded statement as current truth.
The case also reverses a familiar editorial instinct. Instead of cleaning away disagreement so the paper appears inevitable, it treats selected disagreement as part of the evidence explaining why the final argument is no longer identical to its origin.
14. Conclusion
The project began with the metaphor We are code that breathes. Under criticism, the metaphor became less important than the transformations it triggered.
Biological wording was narrowed. Historical language was refined. Prior art removed broad novelty claims. Independent convergence created an attribution problem. Semantic uncertainty produced a non-inference rule. Generative AI participated materially in analysis and reformulation. The paper consequently became an instance of its own research question: how can a claim change without losing the evidence of why it changed?
PRCEP is the resulting protocol candidate. Its possible contribution is not the invention of provenance, belief revision, relational cognition, or Human–AI interaction, but an integrated workflow for preserving claim transitions across human, model, public, literature, and versioned-artifact boundaries.
A research artifact can be designed to preserve not only what it claims now, but the inspectable history of why it stopped claiming what it claimed before.
The next scientific step is independent evaluation using provenance-rich and matched-information control conditions. If PRCEP does not materially improve attribution, correction visibility, transition reconstruction, and independence discrimination relative to its cost, it should be simplified or rejected.
The metaphor opened the discussion. The correction history became the method.